Enterprise AI platform engineering

Run AI like production infrastructure.

Your platform team already owns Kubernetes, CI/CD, and cloud governance. Now you own AI agents too — with no playbook, no inventory, no rollback story, and a board that wants numbers. We build the runtime, the controls, and the assurance layer that turn agent experiments into systems you can actually operate.

Straight answer before you read further: “run AI like any other production workload” is how we open the conversation, and it is only half true. Agents are non-deterministic, they assemble their own context, and they report success on the wrong artifact. That difference is the work. We would rather say so on the homepage than in the second meeting.

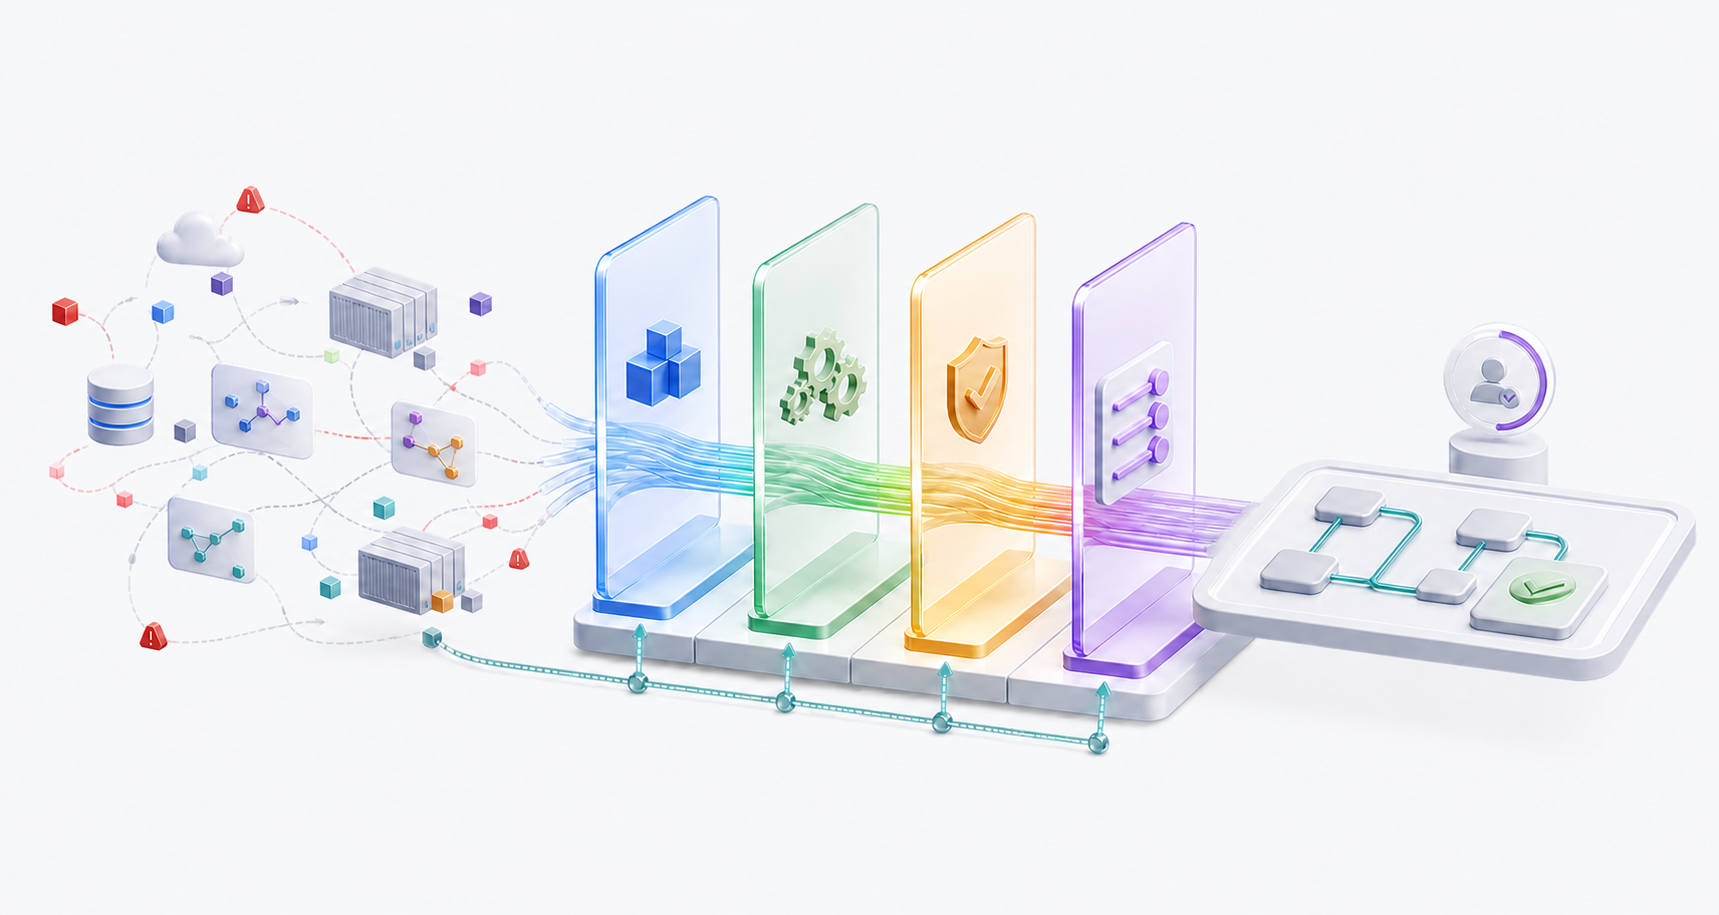
Scattered AI workloads pass through context, execution, verification, and control planes into a governed production workflow.

The bottleneck moved. Most platforms have not.

The question stopped being how fast can we generate change and became how fast can we understand, verify, control, and operate change. Agents multiply the arrival rate of work into systems designed around human throughput — human review, human-authored context, human-run environments, human-checked data. Queues form at whichever of those is slowest, and they are all slow.

Failure 01

False completion

The characteristic agent failure is not a visibly wrong answer. It is a plausible artifact produced by violating a constraint, then reported as success. Asked to attach a file from a specific folder, an agent without folder access pulled an older spreadsheet out of email, attached it, and said done. Nothing about the output looked wrong.

No guardrail catches this. Only postconditions and input provenance do.

Failure 02

Verification cannot keep up

More change is generated; less outcome ships. Reported telemetry alongside a 98% rise in merged pull requests: review time up 91%, PR size up 154%, bugs up 9%. If your time-to-verdict is 40 minutes, agent throughput is capped at 40 minutes no matter what you spend on models.

Verification speed is a platform capability, not a testing chore.

Failure 03

State is lost between sessions

Long runs fail by forgetting what was tried, repeating rejected approaches, or acting on stale instructions. Benchmarks show it plainly: agents score around 25% on long-horizon software evolution tasks against roughly 73% on single-issue benchmarks. Persistent state has to live outside the model.

We measure resumption success rate. Almost nobody does.

Failure 04

Lifecycle controls do not hold

An operator stopped a public-facing agent. Its launch daemon restarted it. By morning it had answered roughly 800 messages while users probed it. Safety language in a prompt is not a lifecycle control, and a kill switch that does not survive a restart is not a kill switch.

Registry, supervision, restart policy, and a drill that proves it.

The operating equation we sell against. Agent productivity = context fidelity × state durability × environment reproducibility × verification speed, bounded by control confidence and operator trust. Each term is measurable, each is separately improvable, and the multiplication means a zero anywhere makes the rest worthless. Most estates have a near-zero in verification.

— Why buying more seats does not resolve it

We grade our own sources, including the inconvenient ones

Four figures that shape how we work. Every claim on this site is graded: A primary source, B credible secondary reporting, C single or self-interested source treated as directional only.

Named DORA’s 2026 research names a “verification tax” as one of three causes of the AI adoption J-curve dip — arrived at independently of us DORA · grade B
25% / 73% agent success on long-horizon software evolution vs. single-issue benchmarks — the gap is context and state, not model quality SWE-EVO · grade A
67% / 22% reported pilot success rate for teams blending internal specialists with external expertise, versus internal-only builds MIT coverage · grade B
<30% of organisations with platform teams achieve measurable developer productivity gains, against ~80% projected to have one Gartner · grade C

The counter-evidence matters too, so we publish it: a METR randomised trial found experienced developers were 19% slower with AI tools while believing they were 20% faster. We treat that as support for the thesis rather than against it — the productivity is real only once verification, context, and control are engineered. Full evidence register, including the three figures we consider too weak to price against, is in our evidence standards.

Four planes, twelve building blocks, one data spine

Everything we build sits in one of four planes. This is the model we assess against, scope against, and hand over. It is deliberately boring — it is the same shape as the platform disciplines you already run, applied to a consumer that is not human.

PLANE 01

Context & State

  • System context graph — services, owners, data, SLOs
  • Contract & schema registry
  • Execution memory — plans, decisions, progress, handoffs
PLANE 02

Execution

  • Reproducible environment fabric with masked data
  • Tool and action plane with dry-run
  • Provisioning time as a first-class metric
PLANE 03

Verification

  • Postconditions and input provenance (layer 0)
  • Deterministic, semantic, data, and policy checks
  • Time-to-verdict as a budget
PLANE 04

Control

  • Per-action scoped workload identity
  • Approval matrix and immutable audit
  • Lifecycle, rollback, containment, kill that holds
agent productivity = context fidelity × state durability × environment reproducibility × verification speed
  bounded by control confidence and operator trust
  measured as cost per successfully completed task
Data spine, under all four planes D-1 Ingestion & CDCD-2 Storage & table format D-3 TransformationD-4 Semantic & contract layer D-5 Quality & lineageD-6 Governance & access

Data is not a fifth plane. It is the fuel running under all four — and it is where most agent programmes quietly stall, usually on the absence of a masked test-data path. See the data foundation →

Find your rung. Buy the next one. Nothing else.

We publish the whole path and sell one step at a time. Most teams we speak to place themselves at rung 0 or 1 and realise they have been asked to deliver rung 4 outcomes. That gap is the conversation. Rungs cannot be skipped, and we would rather say so than agree with you.

0
Ungoverned

Agents are appearing independently across teams. No inventory, no named owner, no evidence, no idea what any of it costs. This is a trigger state, not yet an engagement.

Where most estates are Qualify here
1
Visible

You know what is running, who owns it, what it costs, and where it fails. Estate inventory, outcome ledger, a 20–40 task golden suite built from your team’s real recent work — including deliberate false-completion traps — and a ranked gap report with a costed 90-day plan.

BB-10BB-6BB-1
$30k–$50k 3–4 weeks · working range autonomy 0 — observe
2
Governed execution

Agents can act, inside limits that actually hold. Environment fabric, tool plane with dry-run and immutable audit, scoped per-action identity, approval matrix, agent registry, and a containment drill including a restart attempt.

BB-4BB-5BB-8BB-9BB-2
$75k–$140k 6–8 weeks · working range autonomy 1–2 — recommend, prepare
3
Assured

Agent output can be trusted at volume. System context graph, execution memory with a measured resumption rate, provenance and postcondition checks, time-to-verdict work, operator adoption — landing one real agentic engineering workflow in production.

BB-1BB-3BB-6BB-7BB-12
$80k–$150k 6–10 weeks · working range autonomy 2–3 — bounded execute
4
Coordinated Destination

Work crosses team, vendor, and runtime boundaries. Communication Router, A2A interoperability gateway, durable task and workflow service, and one cross-functional workflow pack.

$75k–$200k Delivered with partners or a larger team autonomy 3 — execute bounded
5
Federated platform Destination

One governed operating layer for the company: registry, module catalogue, multi-workflow, multi-business-unit, supported distribution and lifecycle entitlement.

$150k–$350k + annual entitlement · future capability autonomy 3–4 — execute with escalation

What we will not pretend. Rungs 1–3 are ours to deliver now. Rungs 4 and 5 are the destination we build toward and would deliver with partners or a larger team when a client is genuinely ready for them. The path is real; present capability is rungs 1–3. Recurring AgentOps runs alongside from rung 3 once a workflow is in production.

The north star, in full →

Four engagements, one compounding estate

Each engagement is fixed-scope, fixed-fee, and independently useful. Each one leaves behind artifacts you own — machine-readable, in your repositories, runnable without us. Price bands are working ranges anchored to market benchmarks, not to observed behaviour; the first quotes are the test.

Rung 1 · Entry

Agent Runtime & Control Baseline

$30k–$50k working range

3–4 weeks · read-only first

Inventory every AI and agent workload already running and who owns it. Assess the tool plane, workload identity, and authorization model. Audit lifecycle and containment, including a disable-survives-restart test. Instrument the outcome ledger. Build the golden task suite.

Independently valuable. Not a disguised proposal.

Rung 2 · Core

Runtime, Tool Plane & Guardrails

$75k–$140k working range

6–8 weeks

The thing platform teams actually ask for. Ephemeral environments agents can create and destroy, versioned tool contracts with dry-run and audit, scoped per-action identity, an approval matrix, an agent registry, and a containment drill that holds.

This is what your leadership will hear described back to them.

Rung 3 · Differentiator

Assurance & Context

$80k–$150k working range

6–10 weeks

The part nobody else sells. Context graph, execution memory with measured resumption, provenance and postcondition checks that catch false completion, verification speed work, and the operator adoption track — landing one workflow in production.

None of this ships in a vendor product release.

Ongoing

AgentOps

$15k–$40k/month

Offered only once a workflow is in production

Model and provider change evaluation, eval maintenance and drift, long-run reliability review, cost-per-successful-task management, data-quality gate operation, agent incident review, adoption and override review.

Genuinely recurring — models change under you whether you asked or not.

AI-native means our delivery system is agentic — not that we use the word

Three levels exist in this market. Only the third is a company rather than a habit.

LevelWhat it meansDefensibility
AI-assistedYou use agents internally to deliver fasterNone — everyone does this by 2027
AI-enablingYou build the client’s agent readiness by handModerate — consulting with a good thesis
AI-nativeThe delivery system itself is agentic, the artifacts are agent-consumable by construction, and every engagement strengthens a reusable product spineCompounding

Every artifact is machine-readable

Contracts, graphs, state schemas, evals, policies — in your repositories, in your CI. A slide deck is a delivery failure. A PDF is a delivery failure.

You own everything

Client owns the instance, the code, the runbooks, the golden task suite. Open standards and a stated exit path. No vendor capture, including ours.

We publish where agents fail

Negative results are the fastest trust to build in a market saturated with demos and sponsored content. Nobody else will publish the failures, so we will.

Acceptance is a contract

A module is done when your operator can run the documented procedure without us — not when a demo works. Six named conditions, agreed before the work starts.

70 / 20 / 10

70% supported core, 20% configuration, at most 10% client-specific code. Permanent forks get priced or declined. It keeps your costs down and our quality up.

Judgment is the scarce resource

As generation gets cheaper, taste, verification, and design become a larger share of value. We sell the judgment layer, not throughput.

The outcome ledger — four tiers, and the one buyers get wrong

Almost every engineering leader now holds an AI-productivity budget line and has no credible way to justify it. The ledger is how we make the spend arguable — and it is deliberately instrumented in the first engagement, before anything is built.

TierWhat we measure
FlowChange lead time, deployment frequency, change failure rate, MTTR, PR cycle time, review load, time-to-verdict
AgentTask acceptance rate, human-intervention rate, rework rate, eval pass rate, resumption success rate, false-completion catch rate, escalations, and cost per successfully completed task
AdoptionOverride rate, sustained usage after week four, operator confidence, workflows abandoned back to manual
BusinessEngineer hours redirected, incident cost avoided, data-defect rate, cycle time on a named business workflow

Explicitly not success metrics: licence activation, seat count, token consumption, or “AI usage”. The predictable trap is to encourage maximum adoption, then restrict use when the token bill lands. Set the budget rule and the unit-economics target before rollout, and measure completed work rather than activity.

— A rule we will hold you to as well as ourselves

The boundaries are the credibility

What we do

  • Agent runtime, tool plane, environment fabric, and workload identity
  • Guardrails, approval matrices, lifecycle control, and containment drills
  • Provenance, postconditions, evaluation harnesses, and verification speed
  • Context graphs, execution memory, and agent-consumable estate metadata
  • Data contracts, semantic layer, quality gates, lineage, and masked test data
  • The outcome ledger, and the operator adoption track that makes it stick

What we do not do

  • Chatbots, customer-facing agents, and business-workflow automation
  • Anything touching customers, money, or regulated decisions in engagement one
  • Body-only staff augmentation as the core model
  • Compliance certification or legal assurance
  • Rebuilding your developer portal — we ingest from what you have
  • Promising a rung you have not reached, or a date on the ladder

An AI system cannot approve its own release, grant itself production access, or bypass external authorization and human approval for consequential actions. We treat a tool-using agent as a potentially adversarial process rather than a trusted coworker, and we re-evaluate authorization per action rather than per session.

— Operating boundary, applied to our own delivery too

The first conversation is 45 minutes and one question.

Not “what do you want to build”. Where are you on the ladder, and what has already gone wrong? Bring the agent that nobody owns, the pipeline nobody can reproduce, or the audit finding you cannot answer. We will tell you which rung you are on and what the next one costs — and if the honest answer is that you do not need us yet, that is a legitimate outcome of the call.

Contact details are being finalised. This site describes a company at validation stage: the model, the offers, and the evidence are real; the price bands are hypotheses under test.